Core Technologies
ADAS Large Model
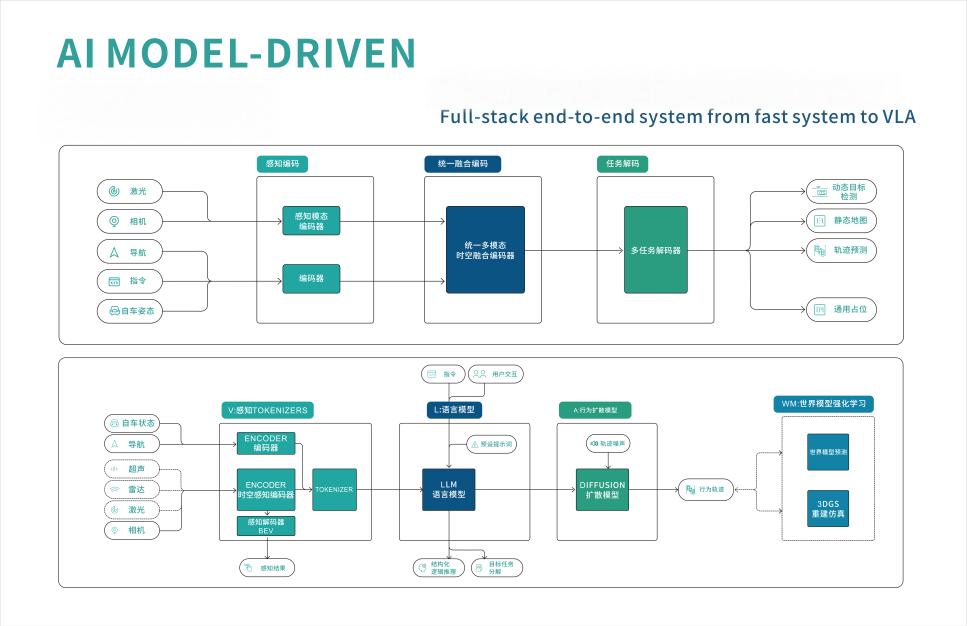
The Multimodal Large Model fuses the World Model with the VLA (Vision-Language-Action) framework: the World Model generates and reasons about driving scenarios, while VLA understands physical causality and common sense and produces actions. The system see
The MOTOVIS VLA basic large model framework is the foundation of cognitive models. It is based on visual encoders, visual language models, and action strategy models, uses the world model as the reinforcement learning environment, and fine-tune with 4D datasets, VQA datasets, regulatory datasets, and physical interaction datasets.